DeepSeek open-sources DeepInfer for large-scale model inference
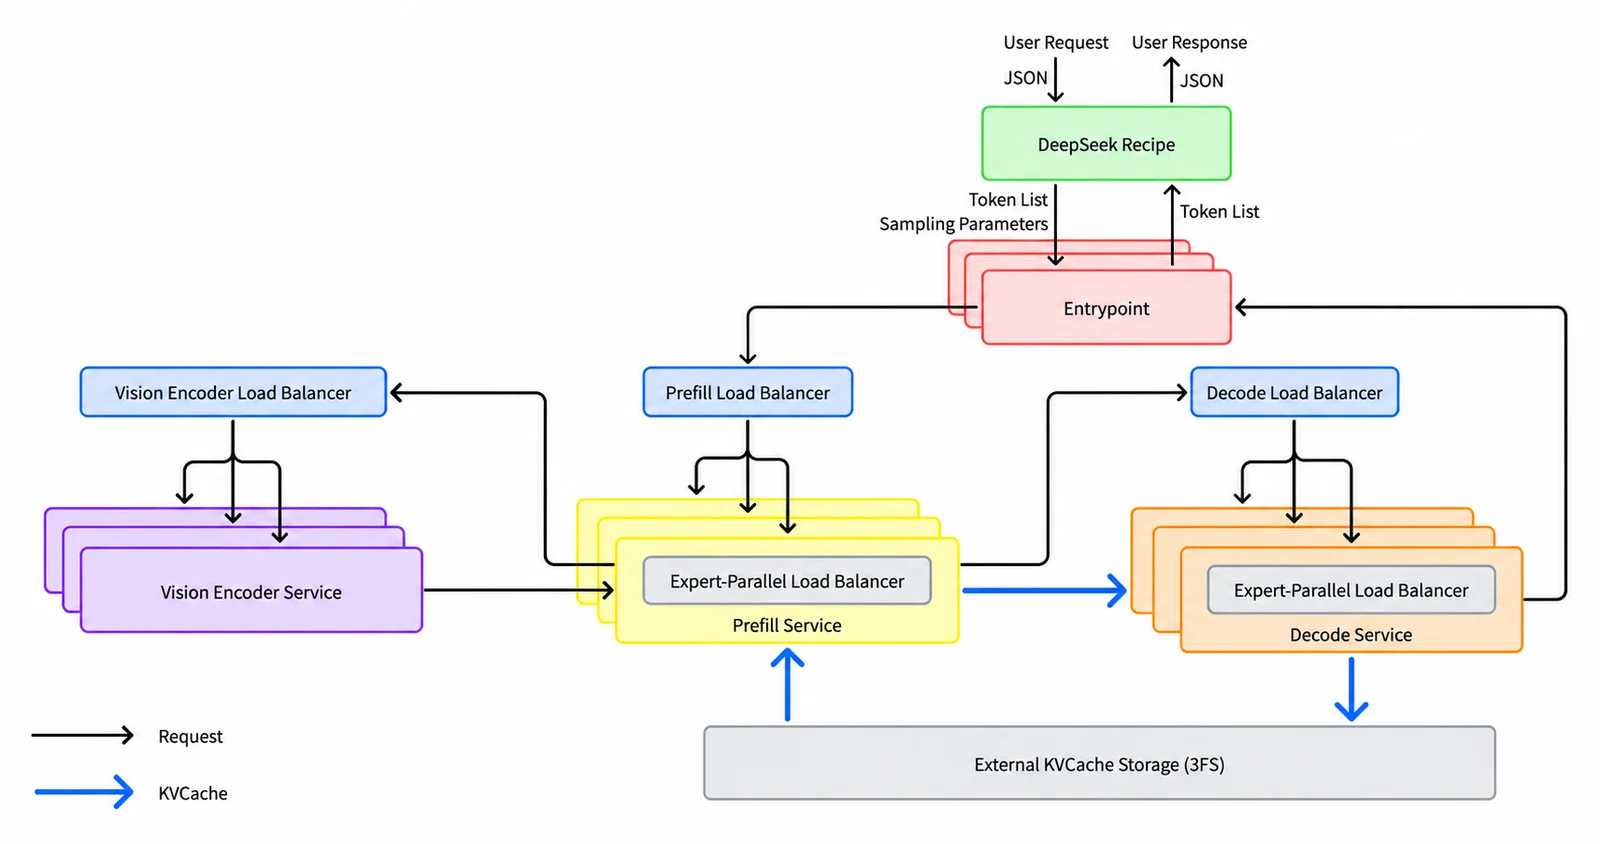
The framework runs V4.1 Flash on NVIDIA and Huawei hardware. Its offline inference core is public, while parts of DeepSeek’s production serving system remain outside the release.
THE DEEPSEEK DESK
Model releases, research and developer updates from DeepSeek.
The framework runs V4.1 Flash on NVIDIA and Huawei hardware. Its offline inference core is public, while parts of DeepSeek’s production serving system remain outside the release.
Search and Fetch give developers another route to bring web information into their AI applications.
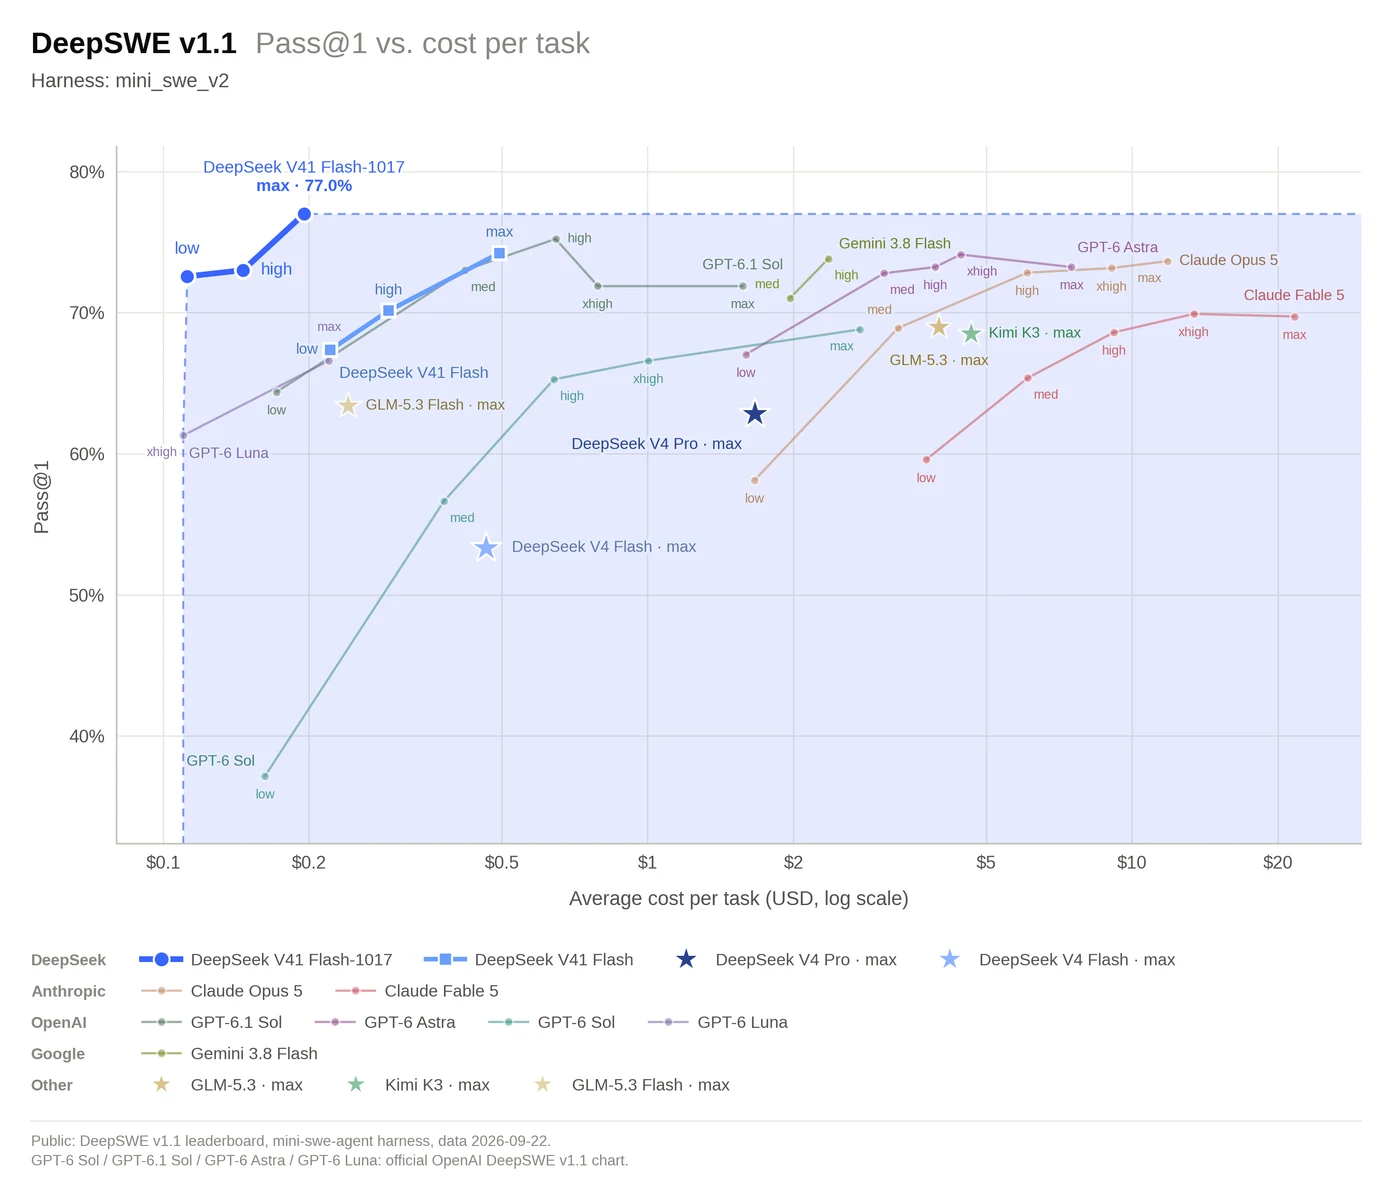
V4.1-Flash-1017 reaches the app, website and API, with DeepSeek reporting shorter task runtimes and stronger results.
The September release changes the architecture and API model name, while a later notice preserves access to V4-Pro.
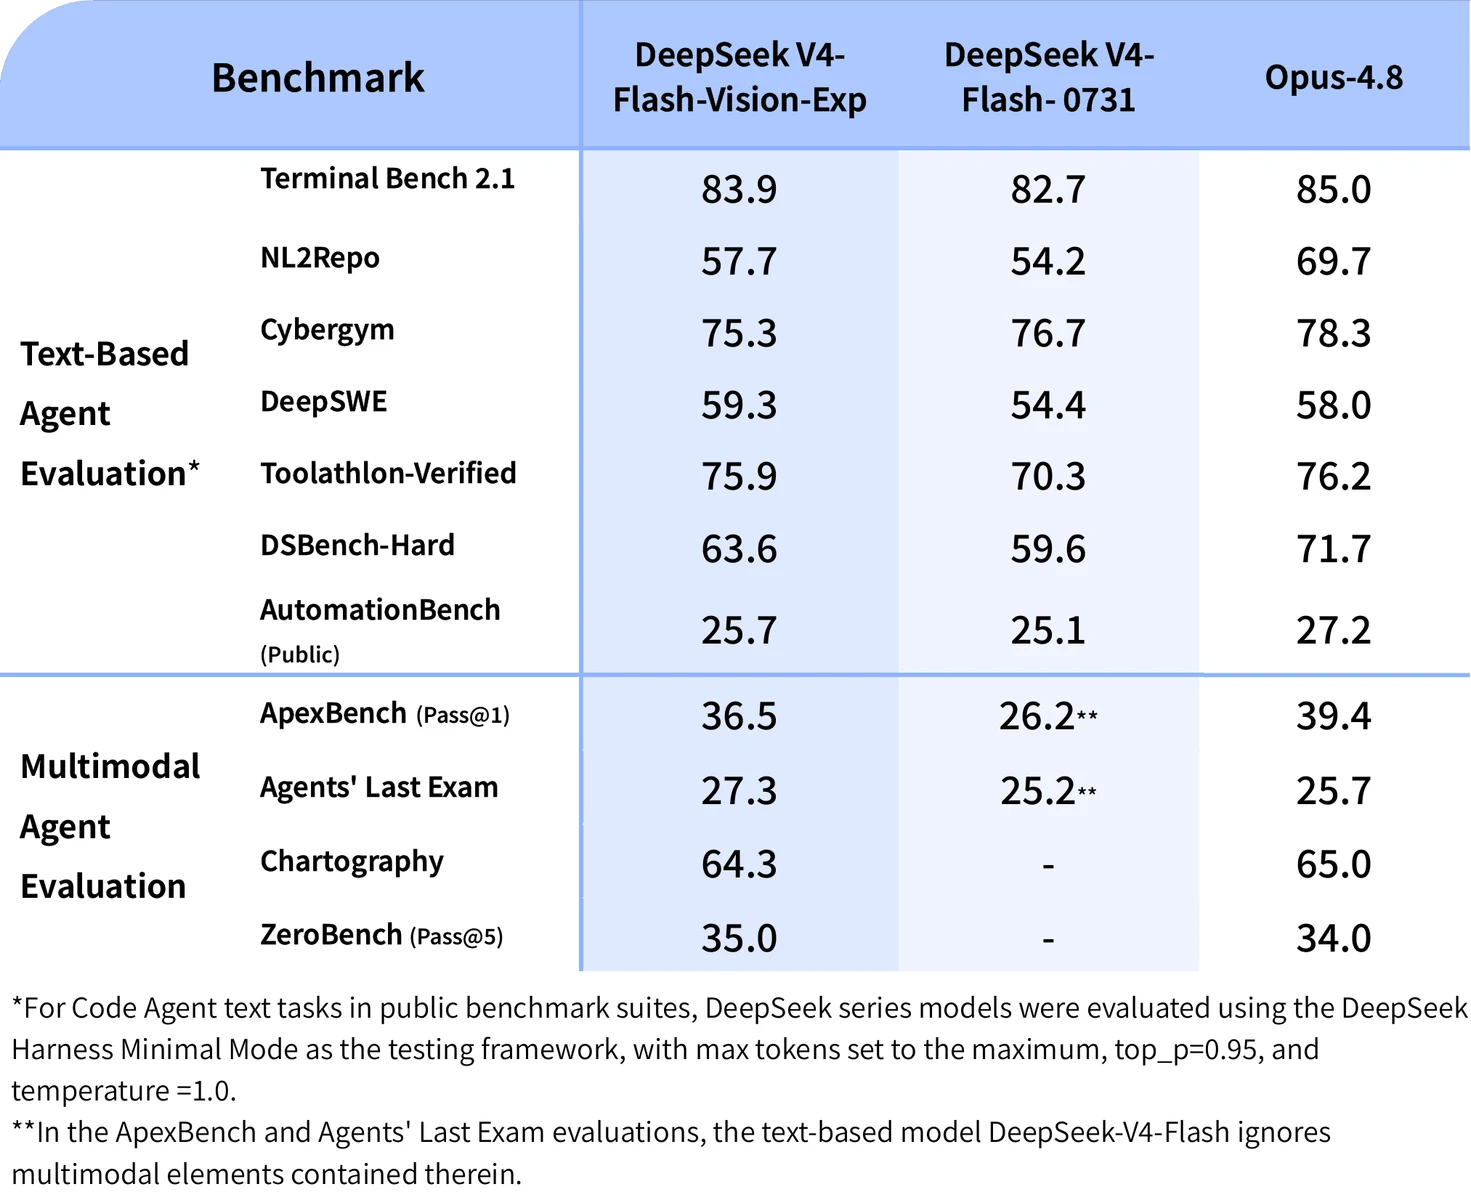
V4-Flash-Vision-Exp brought mixed text and image requests to the API in August; the model has since been superseded.
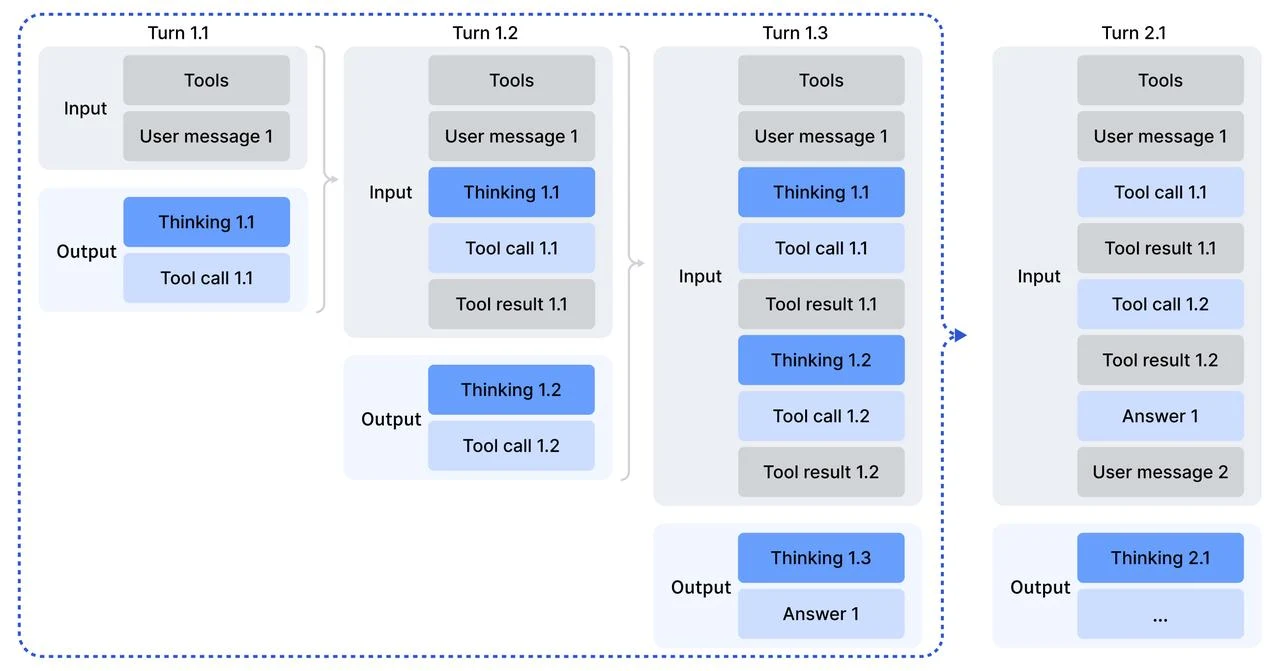
The August release added reasoning controls and native Responses support, alongside a new peak and off-peak pricing structure.
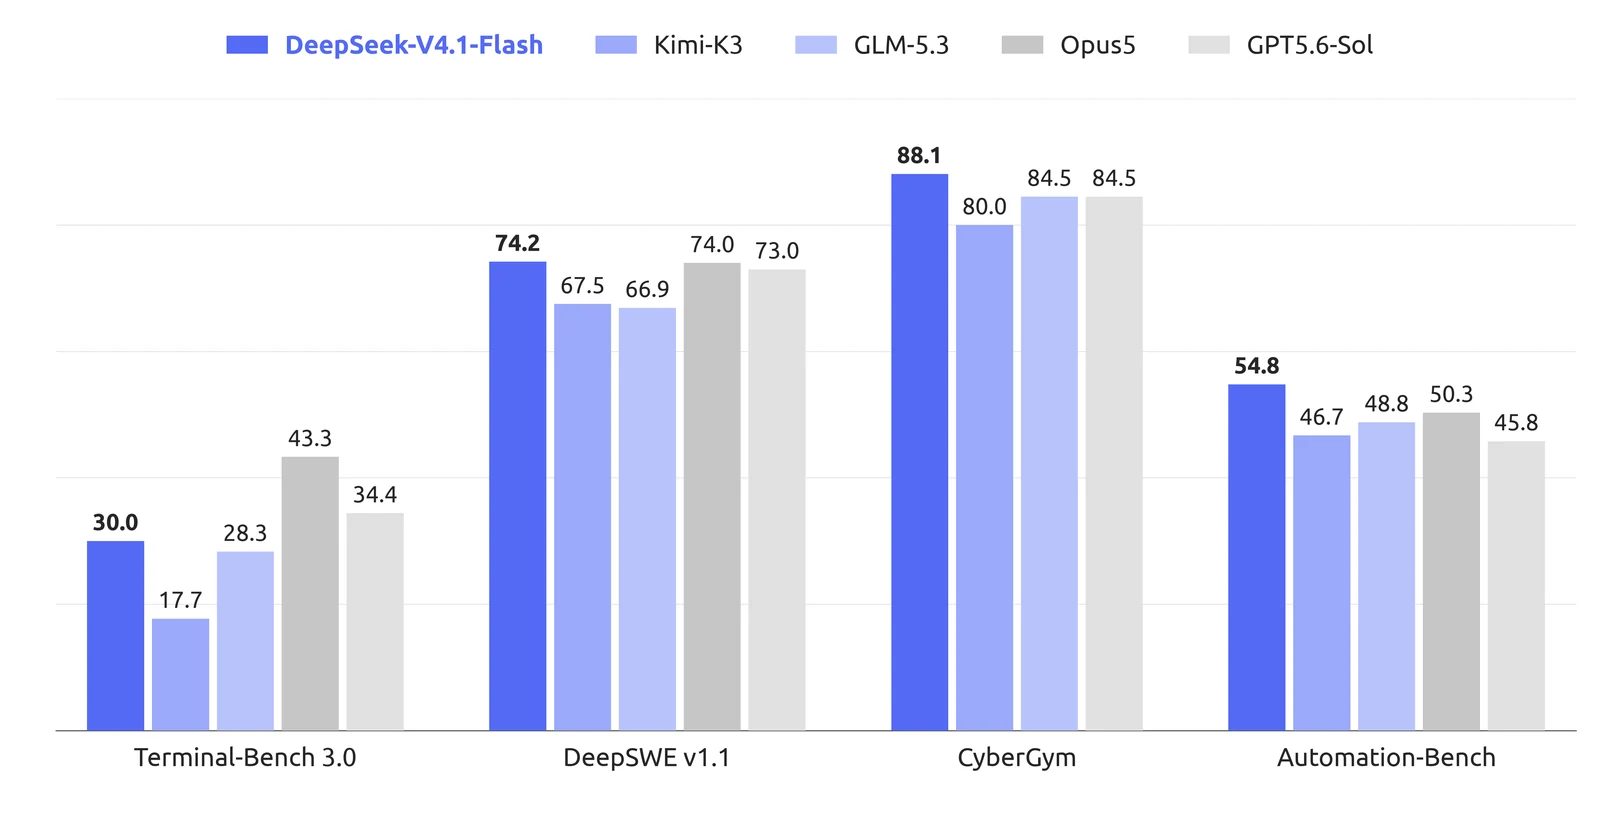
A new post-training run reached the V4-Flash API without changing the model’s size or architecture.
The April release introduced Pro and Flash variants, open weights and updated API model names.
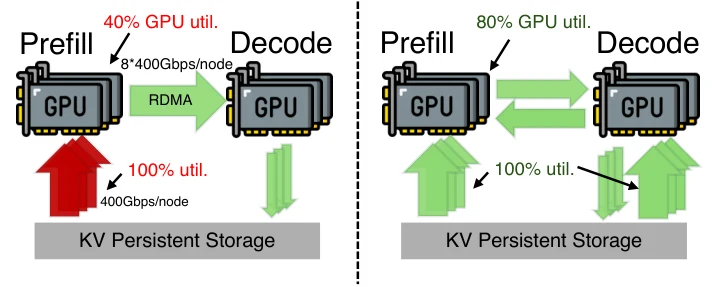
The DeepSeek-listed systems paper adds a second route for loading cached context during multi-turn inference.
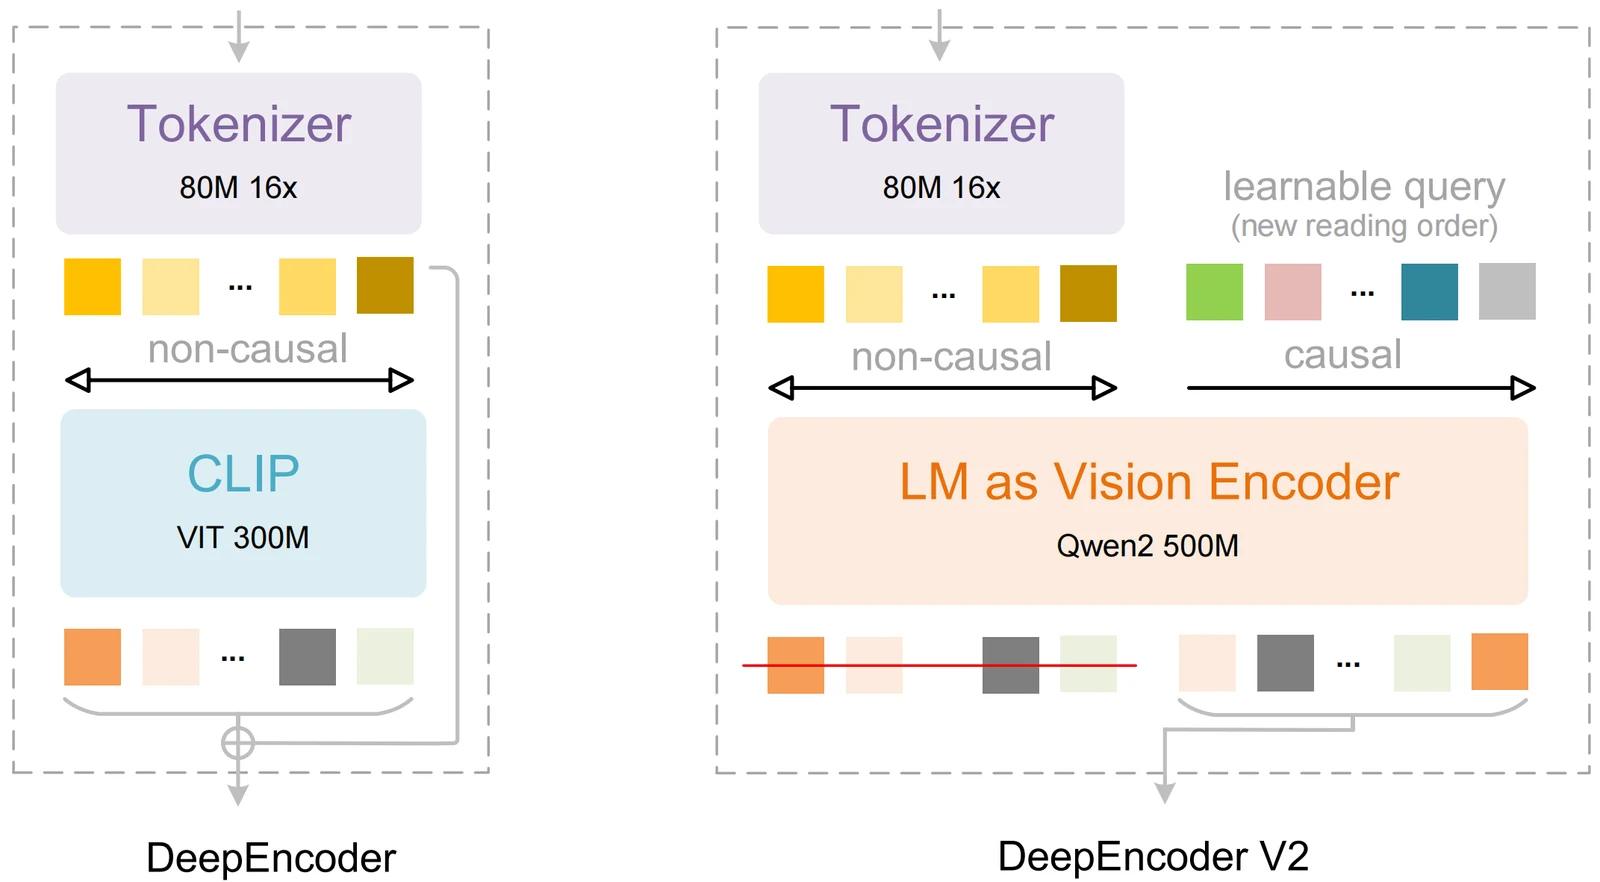
The January research replaces a rigid visual scan with token ordering guided by image meaning.
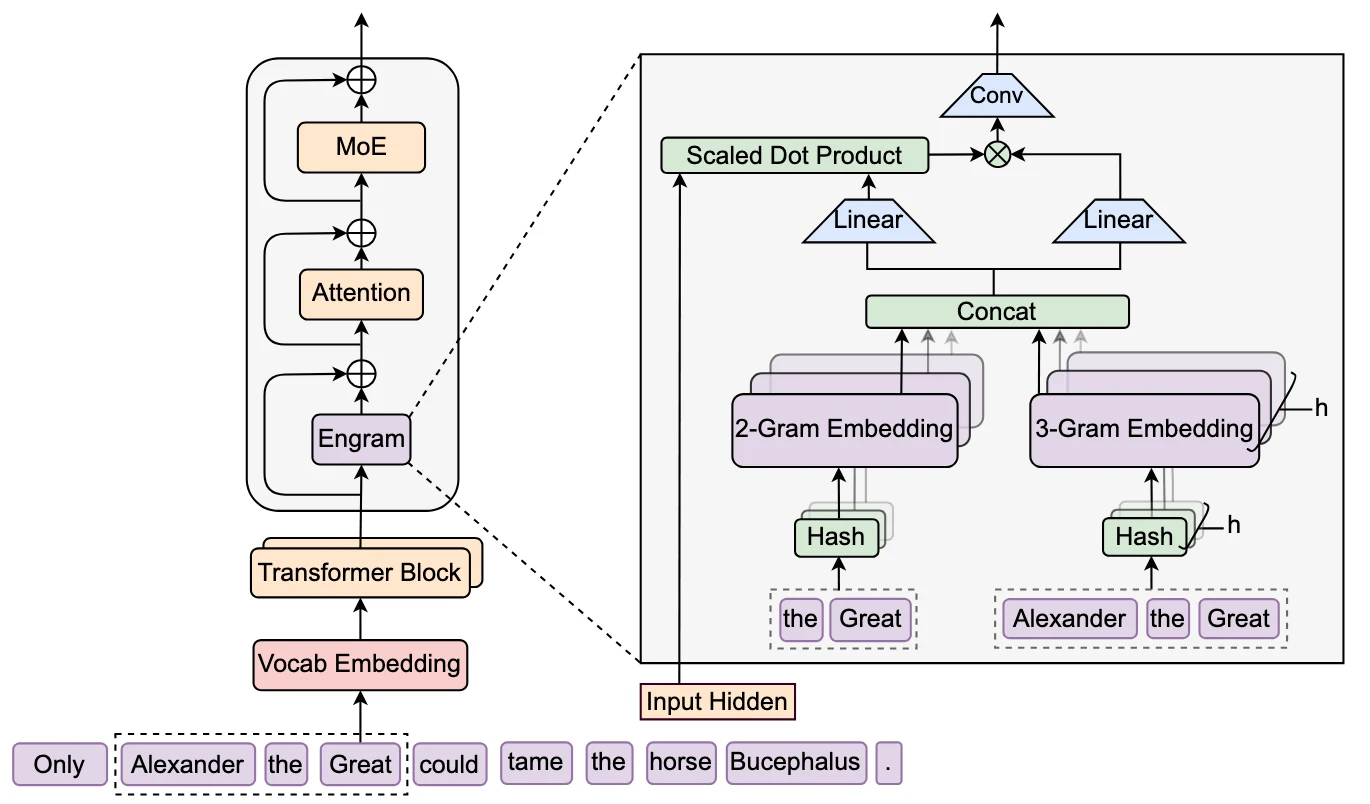
A January paper investigates how static memory and neural computation can share a model’s capacity.
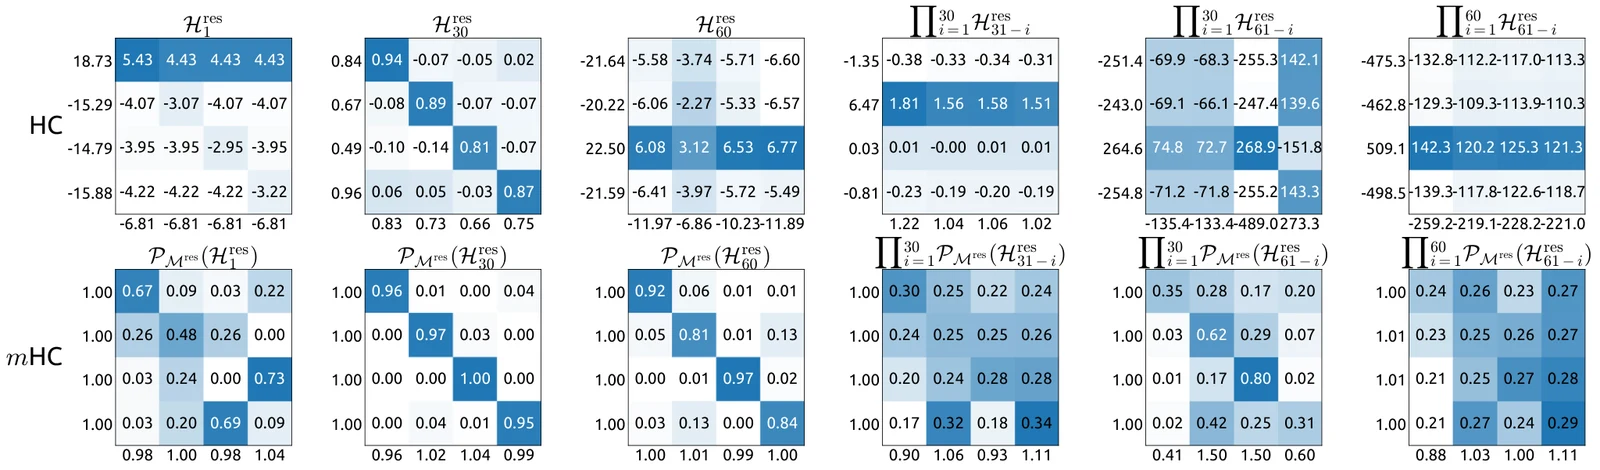
The year-end research proposes constraints intended to keep expanded residual connections stable at scale.
The December release paired a general model with a separate high-compute research variant.
This desk will feature source-linked coverage of DeepSeek.
Browse all stories