DeepSeek opens an experimental vision model for agents
V4-Flash-Vision-Exp brought mixed text and image requests to the API in August; the model has since been superseded.
THE STORY IN THREE POINTS
- The August experiment added mixed text and image inputs.
- It supported three API interface formats.
- September’s V4.1-Flash superseded the experimental model.
The announcement
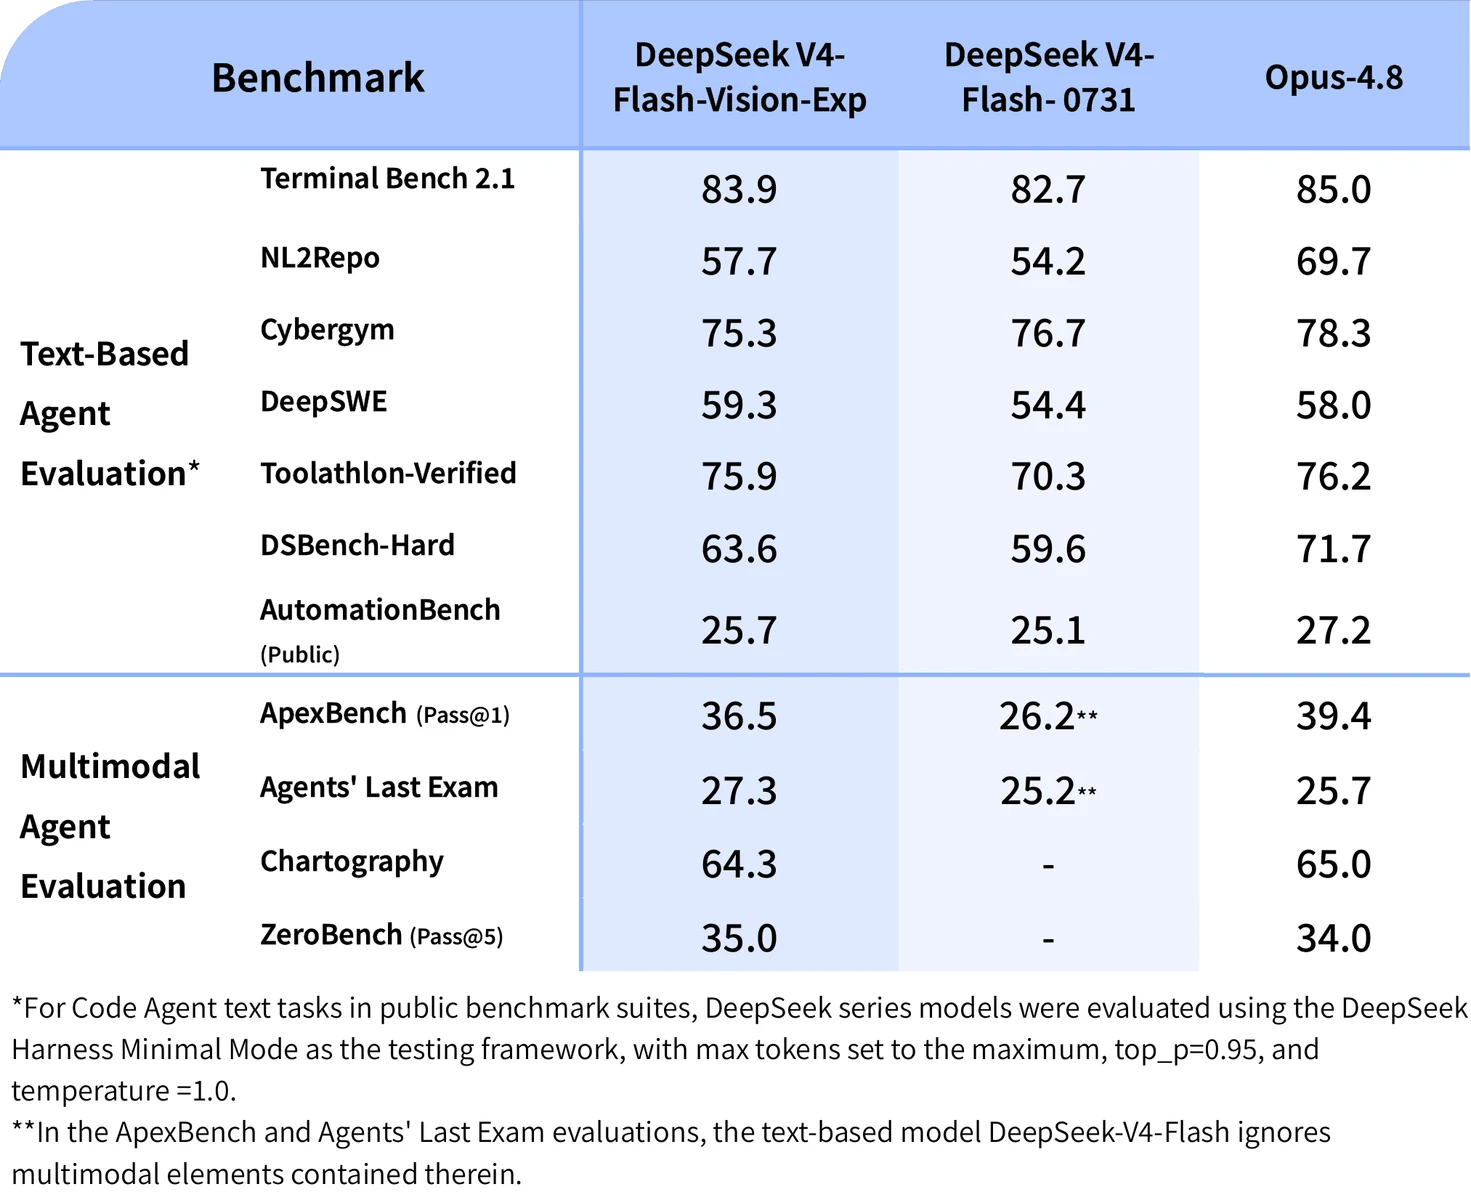
DeepSeek released V4-Flash-Vision-Exp on August 21 as an experimental multimodal API model. The announcement describes mixed text and image inputs through Chat Completions, Messages and Responses, plus reusable image uploads through a Files API. DeepSeek Harness 0.1.1 included support. This is a dated release brief: the September 10 changelog subsequently retired the experimental model and routed its compatibility name to V4.1-Flash.
Editorial context
Images give an agent another source of evidence, but the application still has to decide when that evidence is needed. Sending every screenshot can waste context and obscure a simple text answer. A sensible comparison would test tasks where layout, a chart or a visual interface contains information unavailable in accessible text.
Editorial context: what to watch
Archived examples remain useful for understanding the product’s development, while current integrations should use the replacement model and current documentation. An evaluation could score both correct visual interpretation and successful downstream action. Reading a screen correctly and completing the requested workflow are separate outcomes, so recording both would make a multimodal trial more informative.
Sources: DeepSeek: V4-Flash-Vision-Exp release, August 21 ↗ DeepSeek changelog: September 10 retirement and compatibility routing ↗