DeepSeek-OCR 2 explores a different reading order for images
The January research replaces a rigid visual scan with token ordering guided by image meaning.
THE STORY IN THREE POINTS
- The paper was submitted on January 28.
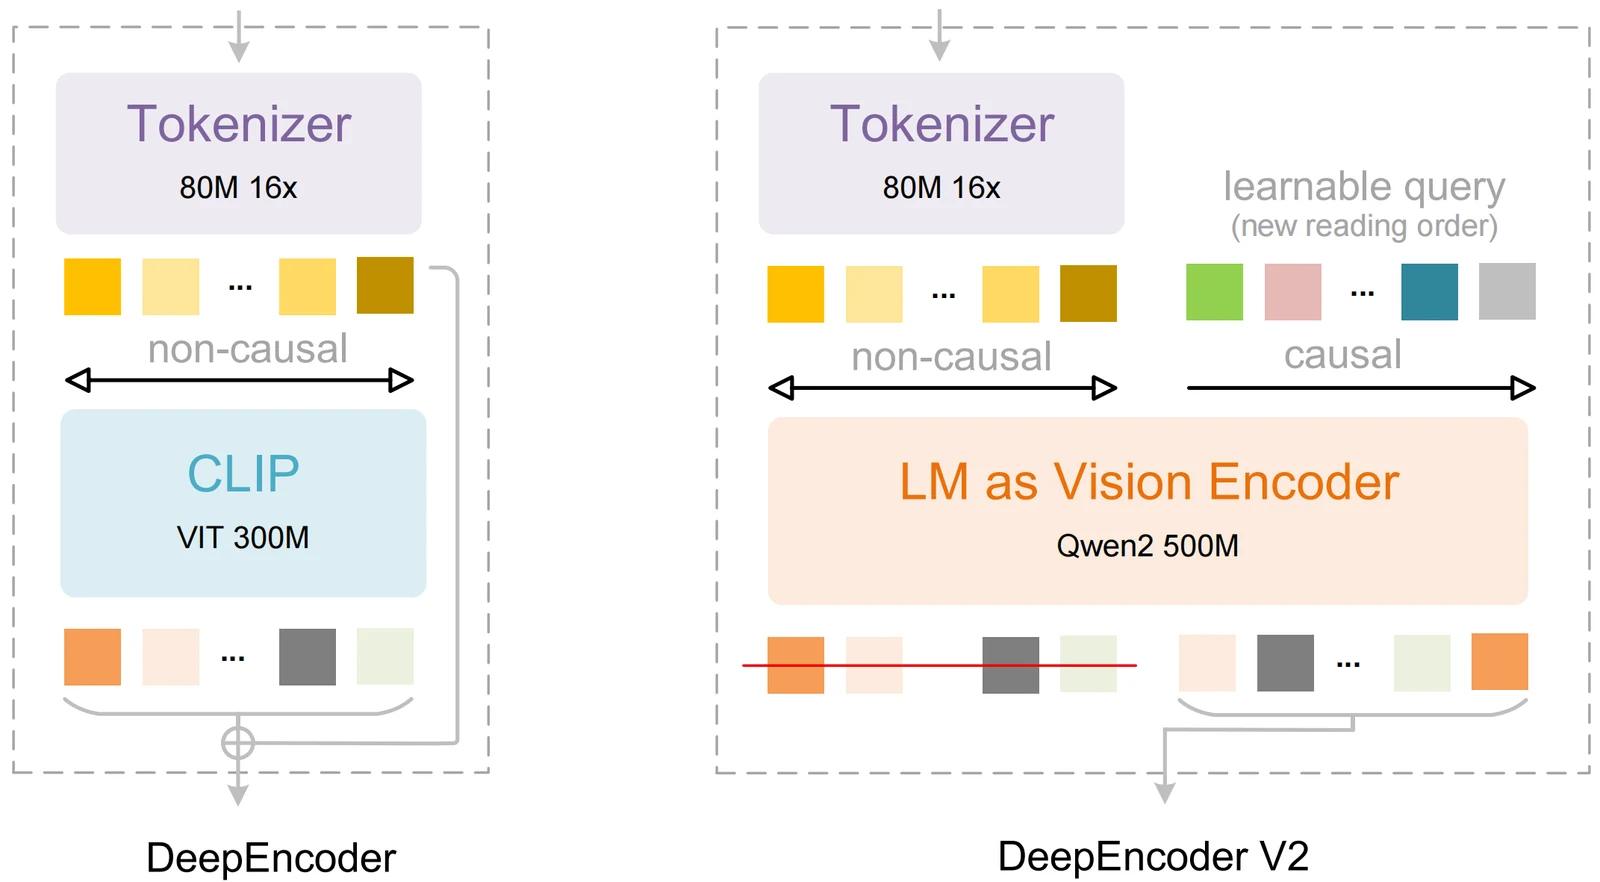
- DeepEncoder V2 reorders visual tokens using semantics.
- The authors provide a public code and weights link.
The announcement
DeepSeek-OCR 2 was submitted on January 28 under the title Visual Causal Flow. The authors introduce DeepEncoder V2, which can reorder visual tokens according to image semantics before language-model interpretation. Their motivation is that complex pages contain logical reading structures that a fixed top-left-to-bottom-right scan may not capture. The preprint links publicly available code and model weights for further investigation and evaluation.
Editorial context
A newspaper page, technical diagram and invoice each imply different relationships between text regions. A reading system can recognize individual words yet connect them in the wrong order. Evaluating layout comprehension therefore calls for questions about headings, captions and table membership, alongside conventional character recognition. That is the editorial significance of exploring visual sequence itself.
Editorial context: what to watch
The next useful comparisons would include unusual columns, rotated text and pages where a caption belongs to a distant image. Test material should preserve its original layout so that a correct answer depends on spatial understanding. The paper proposes an architectural direction; independent document-level tests would show whether it reduces errors in an actual reading workflow.
Sources: DeepSeek-OCR 2 author preprint: January 28 ↗